JOURNAL
Uncensored AI — Research Notes
Research notes on how uncensored AI works: abliteration, GGUF quantization, model lineages, and how to run these models locally — written from public information and primary sources.
日本語TOOLGGUF VRAM calculator — how much memory each quantization needsWriting With an Uncensored AI: Start a Story, Keep It Going
Tense scenes and technical drafts are where assistants stop. Here is how to write with an uncensored AI: brief it first, work scene by scene, and verify.
Read →Why Does an AI Refuse? Four Reasons and What to Do Next
A refusal can come from four causes: a safety check, missing information, an unclear question, or a glitch or message limit. Read the message to find yours.
What Can You Hand to an AI, and What Should You Keep?
Summaries and background reading are easy to delegate. Personal data and publishing raw output are not. Here is where the line sits, and why, in five checks.
Can You Use an Uncensored Model Commercially? What to Check
Most uncensored builds trace back to Apache 2.0 or MIT, but the terms follow the base model and the distributor may add more. Check a model before you ship it.
No-Filter AI: How to Start on Your Phone Without Signing Up
Start a no-filter AI in your phone browser today: no app, no account needed for the first message. Here is how to begin, and what to ask when it refuses.
No-Filter AI: How to Choose and Try One Free
What no-filter AI really means, three checks that separate a usable service from hype, and three prompts that show in ten minutes whether it fits your work.
Uncensored Models for Japanese: How to Read the Scores
Public leaderboards measure Japanese capability, but the ranking does not transfer to real tasks: one meeting-summary benchmark found a −0.52 rank correlation.
How to Ask an AI About a Screenshot or Photo
Screenshots, receipts and handwritten notes can go into a chat as images. Here is how to send one well, get an accurate reading, and what not to photograph.
What to Do When You Hit an AI Limit: Wait, Adjust or Switch
Message limits, content refusals and slow answers behave differently. Here is how to tell which one you hit, what to try first, and how to choose a replacement.
Qwen3-VL Abliterated: Which Uncensored VLM to Run?
Qwen3-VL abliterated builds cover 2B, 4B, 8B and 32B dense models plus a 30B-A3B MoE. Pick one by GPU memory, and GGUF needs a separate mmproj file for images.
How to Run Uncensored Models With Ollama (2026 Guide)
Run an uncensored model with Ollama in two commands. Which abliterated build fits your GPU memory, how to read quantization, and what to check before you download.
DeepSeek Uncensored Builds: V4.1 Flash Abliterated Guide
DeepSeek V4.1 Flash (September 2026, MIT, multimodal) has community uncensored and abliterated builds. Compare the options, formats, and how to pick one.
Qwen3.8-27B Uncensored: Which of 12 Builds to Pick
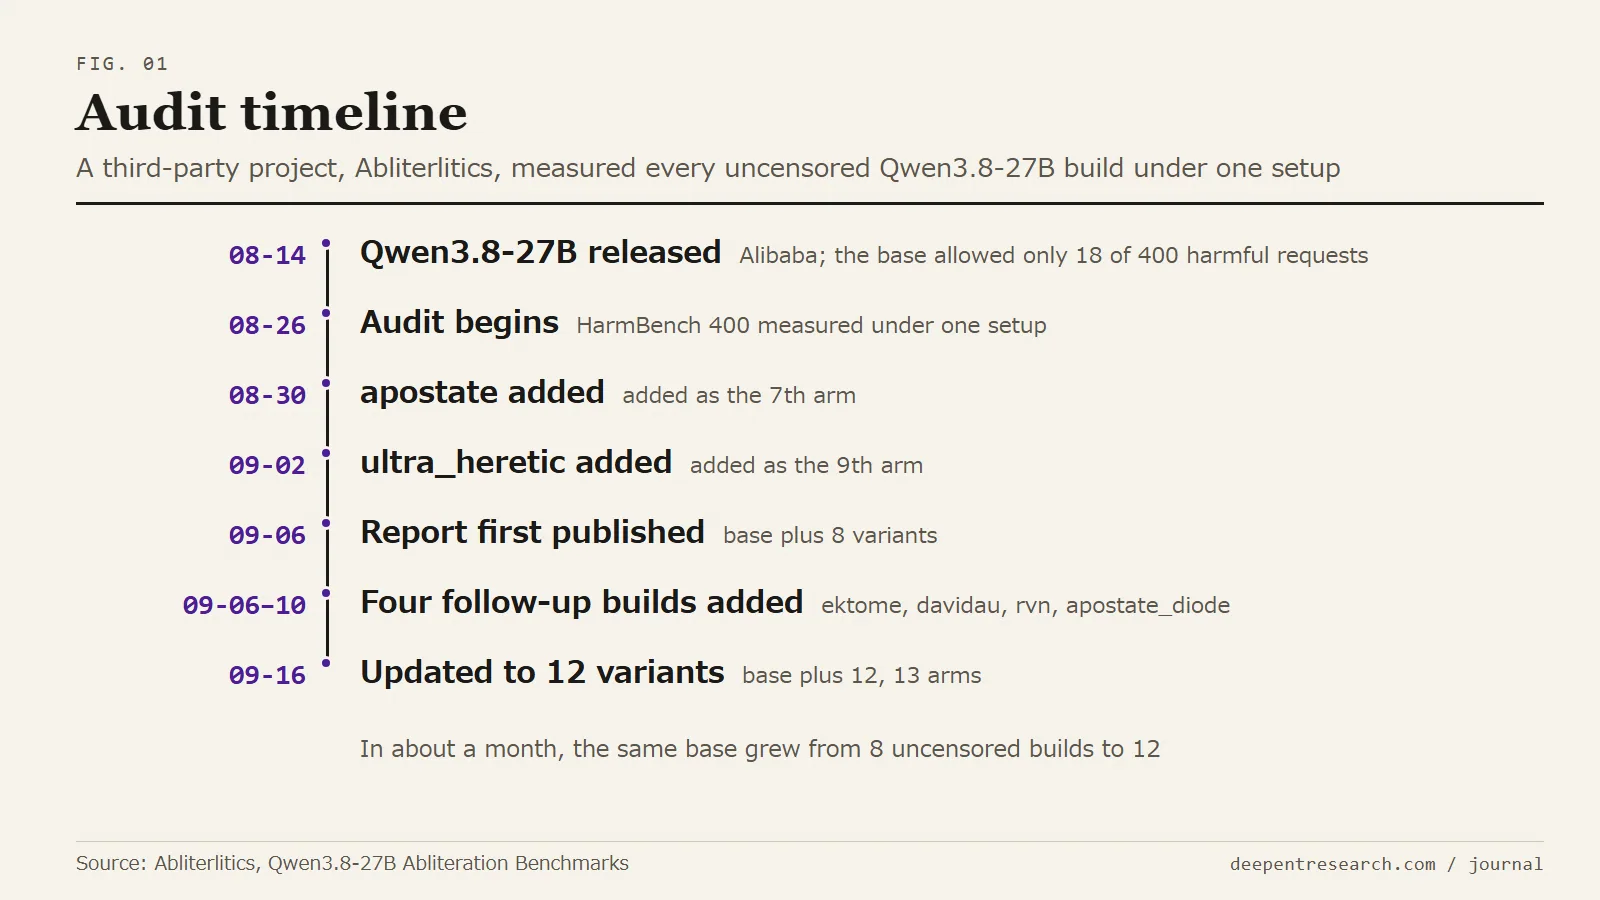
Qwen3.8-27B uncensored derivatives vary widely. An audit of 12 builds shows which models deliver answers, which to avoid, and five checks before running one.
 14
Uncensored LLM Misuse: What the Research Shows
Uncensored LLM misuse is documented: studies found 11,598 and 22,096 models tied to malicious services. What the evidence proves and how to run one safely.
GLM-5.3 Uncensored Builds: Cyber Capability Explained
GLM-5.3 uncensored builds span abliterated weights, GGUF quants, and EXL3 toggles. Compare cyber evaluations from NIST and Anthropic to run derivatives safely.
Qwen3.8-Flash-Next Uncensored: Which Build to Pick
Qwen3.8-Flash-Next uncensored builds span 3 types. Compare abliterated weights, GGUF quants, and MTP builds to pick the right derivative for your hardware.
Gemma 4 Abliterated: 26B MoE vs 31B Dense Guide
Gemma 4 abliterated builds differ by publisher. Compare the 26B-A4B MoE and 31B dense versions by refusal rate and KL divergence, and choose one for your GPU.
Uncensored vs Abliterated: What's the Difference?
Uncensored is the result: a model that doesn't refuse. Abliterated is one way to get there. See how they differ from finetuning, jailbreaks and low guardrails.
Low Guardrail Models: Why Makers Ship Safety Separately
Low guardrail models from Meta, Google, Mistral and DeepSeek fall into three types. Learn how each type works and what to check before you choose one.
Uncensored LLMs: 10 Best Models by GPU Memory (2026)
In 2026, the best uncensored LLM for most people is Qwen3.8-27B abliterated. 10 top picks by GPU memory, plus how uncensored and abliterated models differ.
GGUF Quantization: How to Choose Q4 vs Q8 for Local LLMs
Learn what GGUF quantization is, how to read Q4_K_M, how Q4, Q6 and Q8 compare in accuracy and speed, and what fits your PC, using published Llama 3.1 8B data.
Abliterated Qwen3.8-27B: Compare 4 Editions and Choose
Abliterated Qwen3.8-27B differs by creator. Compare huihui-ai, orcarouter, Heretic and RVN editions by edit range, quantization and published refusal rates.
Nous Research and Hermes: Neutral Alignment Explained
Nous Research grew from a Discord community into an open-weight lab. Learn its Hermes lineage, neutral alignment, how it differs from Dolphin, and use cases.
How to Choose an Uncensored AI: 5 Checks That Matter
Choose an uncensored AI by real behavior, not slogans. Compare hosted, local and downloaded options with 5 checks: refusal data, privacy, model, trial, updates.
What Is OBLITERATUS? Abliteration Toolkit and Model Guide
OBLITERATUS is an open-source abliteration toolkit that maps a model's refusal structure before editing it. Learn its 6-step pipeline and how to choose models.
Local LLM Guide: Run AI on Your PC with LM Studio
A local LLM runs an AI model on your own PC, so your prompts stay private and there is no monthly fee. See hardware needs, model choice and LM Studio setup.
What Is huihui-ai (huihui AI)? Abliterated Models Guide
huihui-ai (huihui AI) publishes abliterated versions of open models on Hugging Face. See popular builds, how to read model names, and which size to pick.
Dolphin Models vs Abliterated: Which Uncensored LLM to Pick
Dolphin models are Eric Hartford's refusal-free LLM series from 2023. Compare them with abliterated models, pick a build for your PC, and set the system prompt.
Is Uncensored AI Legal? Laws, Risks and Safe Use
Is uncensored AI legal? Running public open-weight models is generally not illegal in itself; liability depends on use. Covers risks, minors and safe use.
Uncensored AI Models: How to Use Them and 6 Use Cases
Uncensored AI models keep answering when standard AI refuses a research question. See how they work, six use cases, how to phrase questions, and how to run one.
What Is Abliteration? How LLMs Lose Their Refusals
Abliteration is a weight-editing technique that removes an LLM's refusal habit while keeping its knowledge intact. Learn how it works, in plain English.
Not just reading — try it
Deepent Research is an LLM chat service that refuses almost nothing. Everything covered here can be tried without downloading anything.
Start free →