Qwen3.8-27B Uncensored: Which of 12 Builds to Pick
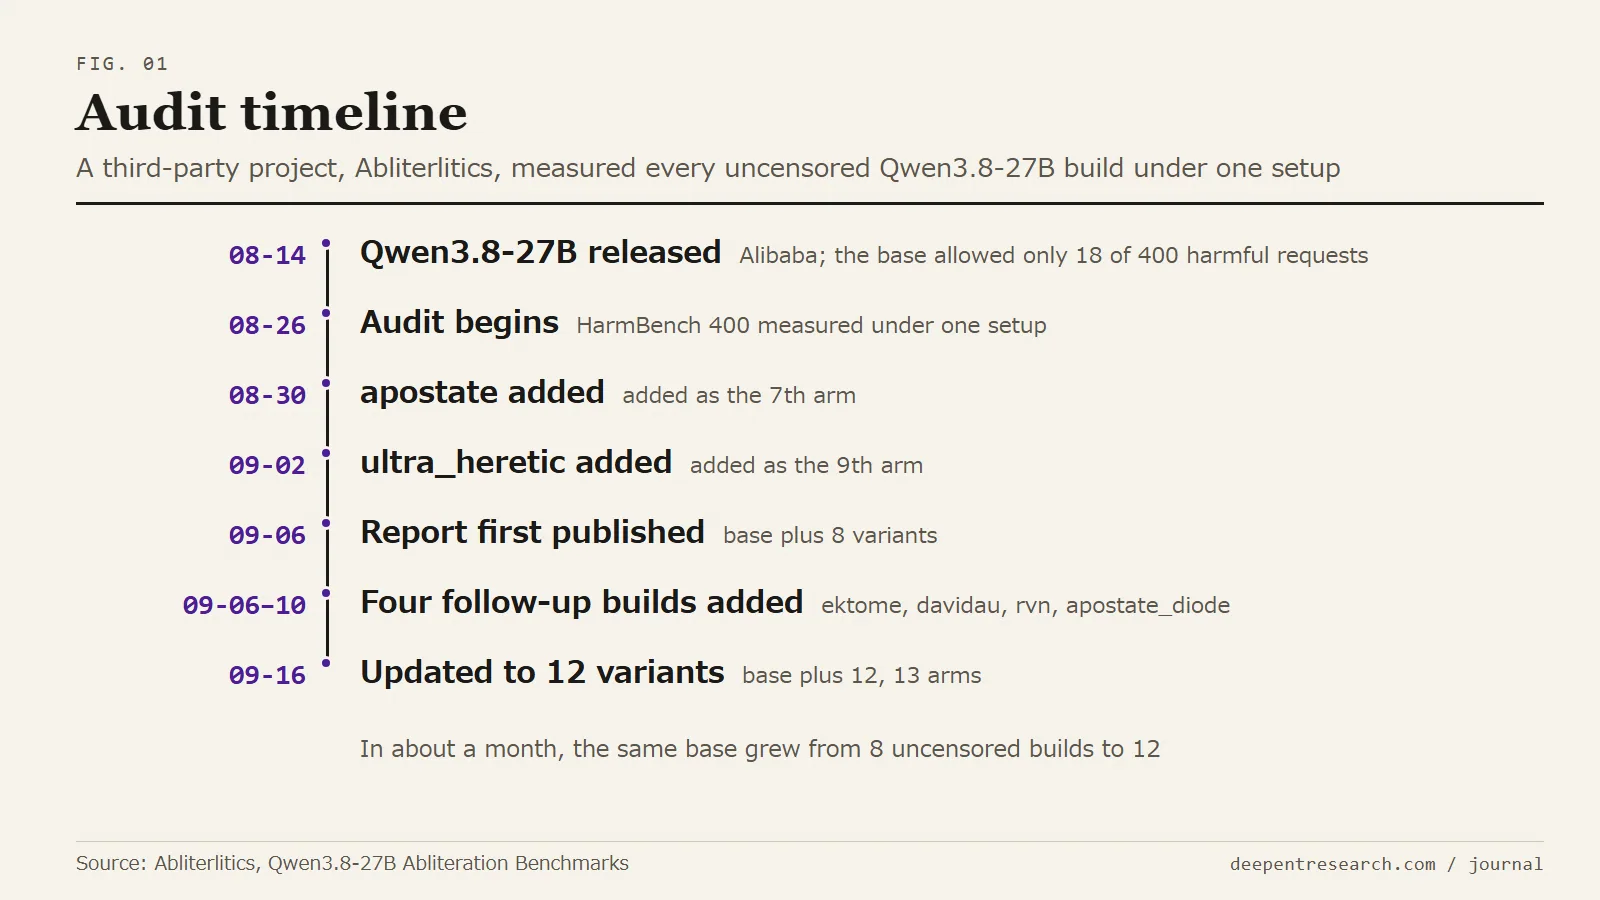
Qwen3.8-27B uncensored derivatives vary widely. An audit of 12 builds shows which models deliver answers, which to avoid, and five checks before running one.
Key points
- A third-party audit showed 12 uncensored Qwen3.8-27B builds differ widely, ranking orcarouter best overall and apostate the least-changed.
- Avoid OBLITERATUS due to severe loops and intelligence loss, and exercise caution with Blackfrost-AI's hidden template jailbreak.
- High refusal removal does not guarantee delivered answers; verify builds using five key checks before downloading.
Contents
- What is an uncensored Qwen3.8-27B build?
- Which uncensored Qwen3.8-27B builds are rated best?
- Which builds should you avoid?
- Why do some builds comply but never finish?
- How should you read the audit numbers?
- How do you check a build before running it?
- What is Deepent Research?
- Frequently asked questions
- Disclaimer
Search Hugging Face or Ollama for an uncensored or abliterated Qwen3.8-27B and you will find about a dozen community builds. They share one base model, yet their quality differs widely. The independent Abliterlitics audit tested 12 of them across roughly 333 GPU-hours and found that light, targeted edits beat heavy ones. The best overall pick is orcarouter, with an 82.2% judge attack success rate. If you want the build that stays closest to the original, choose apostate (formerly heterodoxin), which edits only 41 tensors. trohrbaugh keeps the most original behavior because it refuses some prompts on purpose.
Avoid OBLITERATUS. It edited nearly 99% of its tensors, scored lower on general reasoning benchmarks, and left nearly half its answers stuck in unfinished thinking loops. Be careful with Blackfrost-AI too, which hides a 1,457-character jailbreak inside its chat template. A high refusal-removal score does not mean you get answers, so run five checks before you download a build.
What is an uncensored Qwen3.8-27B build?#
An uncensored Qwen3.8-27B build is a community derivative whose weights have been edited to switch off refusals, without full retraining. The edits subtract refusal directions instead of adding knowledge, so the model answers prompts it would normally decline. The official base model blocks nearly all of them, including legitimate research questions, which is why people turn to these builds.
Alibaba released Qwen/Qwen3.8-27B on August 14, 2026. It is an open-weight model of about 27B parameters on the Qwen3_5ForConditionalGeneration architecture, with 64 layers (48 Mamba2 linear-attention and 16 full-attention), native vision input and an MTP draft head. Its context window is 262,144 tokens (served at 16,384), and its vocabulary has 248,320 entries. Of 400 HarmBench test prompts, the base model complied with only 18 (4.5% judge ASR, 6.0% harmful compliance).
Abliteration subtracts those refusal directions from the weights, as explained in What is abliteration? and Abliterated Qwen3.8-27B: Compare 4 Editions and Choose. To compare the builds, the independent project Abliterlitics audited 12 variants and the base across about 333 GPU-hours on an RTX 5090 32GB, using dynamic FP8 and extended thinking. The audit used 13 benchmarks and 5,200 verdicts from the judge model glm-5.3-flash.
Which uncensored Qwen3.8-27B builds are rated best?#
The audit found that small, careful edits beat heavy ones. orcarouter is the best build overall, with the highest judge ASR of the group. apostate is the least-changed build under the hood, and trohrbaugh is the most intact because it refuses some extreme prompts on purpose.
orcarouter/Qwen3.8-27B-Uncensored leads with 82.2% judge ASR and 96.7% harmful compliance. It used classic single-direction removal (Arditi et al., 2024, k=1) across 129 tensors, with a measured KL divergence of 0.0676 (lower means the weights moved less from the base). All four of its model card claims checked out, and it allowed the highest copyright reproduction, at 39%. heterodoxin/qwen-3.8-27b-abliterated (apostate) made only 41 edits via KCRN, all rank-1, giving a KL divergence of 0.0439 and 78.7% judge ASR. It is text-only, with no vision tower or MTP head.
trohrbaugh/Qwen3.8-27B-heretic-ara used ARA across 60 tensors and refuses 122 of 400 prompts on purpose (57.5% ASR). It has the lowest truncation rate (14.8%) and a KL divergence of 0.0586. Two follow-up builds are also worth knowing: rvn applied two ARA passes across 60 edits (KL 0.0837), and apostate_diode added gated neurons on layers 14–48, giving the lowest measured KL divergence (0.0389, 94.7% compliance).
The audit sorts the builds into three tiers by how much of the model they touched. The smallest, most precise edits cluster at the top, while OBLITERATUS, which rewrote 841 of the model's 850 language-model tensors, lands at the bottom. Tensor counts are edits out of those 850 LM tensors, as reported by Abliterlitics.
| Tier | KL divergence | Builds (tensors edited) |
|---|---|---|
| Surgical | 0.04–0.07 | trohrbaugh (60), apostate_diode (41), orcarouter (129) |
| Standard | 0.05–0.08 | huihui-ai (70), coder3101 (88) |
| Aggressive | 0.17–1.54 | ultra_heretic (99), Blackfrost-AI (124), OBLITERATUS (841) |
Which builds should you avoid?#
Avoid OBLITERATUS. It edited nearly all of the model's tensors, scored lower on several benchmarks, and left nearly half its outputs stuck in unfinished thinking loops. Be careful with Blackfrost-AI, which hides a long jailbreak prompt inside its chat template, and with ultra_heretic, which falls in the aggressive tier where factual accuracy dropped noticeably.
OBLITERATUS/Qwen3.8-27B-OBLITERATED was the benchmark's clearest failure. It edited 841 tensors (98.9% of the model) and pushed KL divergence to 1.5427. In 44.8% of responses the model never finished thinking, and 40.8% were truncated at the token limit. It was the only variant that got meaningfully dumber (MMLU-Pro -6.3pp, IFEval -4.4pp, TruthfulQA -11.2pp), though its math held up.
Blackfrost-AI/Qwen3.8-27B-ABLITERATED-BF16 (KL 0.1694) needs the same caution. It does not disclose its method, and its chat template hides a 1,457-character jailbreak prompt that forces an obedient persona. On the stock template its compliance dropped, with a persistent 2.5% refusal floor. ultra_heretic reached a KL divergence of 0.2996, which fits the audit's finding that heavy edits hurt truthfulness on TruthfulQA first.
Why do some builds comply but never finish?#
A build can agree to a sensitive request and still fail to deliver a usable answer. In a thinking model, the response can loop in its own reasoning until it hits the token limit, so the answer never arrives. Raw compliance rates overstate how useful a build is unless you also check how many responses finish.
High compliance figures often hide these failures. ektome has the highest harmful compliance, at 98.3%, but 30.8% of its responses were truncated, and only 68.1% were delivered. huihui-ai complied with 98.0% of harmful prompts across 70 modified tensors, yet 40.0% of its responses were truncated (160 of 400 prompts), which cut delivered output to 58.8%.
| ektome | 98.3% | |
|---|---|---|
| huihui-ai | 98% | |
| orcarouter | 96.7% | |
| apostate | 95% | |
| apostate_diode | 94.7% | |
| davidau | 92.7% | |
| ultra_heretic | 92.7% | |
| rvn | 92% | |
| Blackfrost-AI | 91% | |
| OBLITERATUS | 84.9% |
| davidau | 85.3% | |
|---|---|---|
| apostate | 71.9% | |
| orcarouter | 71% | |
| rvn | 70.2% | |
| ektome | 68.1% | |
| apostate_diode | 67.9% | |
| huihui-ai | 58.8% | |
| OBLITERATUS | 50.3% |
As the charts show, willingness to answer does not guarantee delivery. davidau finishes the most responses (85.3%), followed by apostate (71.9%) and orcarouter (71.0%).
How should you read the audit numbers?#
Start with KL divergence, which shows how far an edit moved the model from its base; lower means a smaller edit. Then compare each model card's claims with the independent measurements, because cards often understate divergence. Expect copyright refusals to remain, since every build kept most of them.
KL divergence measures how much the model's probabilities shift relative to the base, so lower values mean more surgical edits. The measured order is:
apostate_diode (0.039) < apostate (0.044) < huihui-ai (0.053) < trohrbaugh (0.059) < orcarouter (0.068) < rvn (0.084) < coder3101 (0.084) … Blackfrost-AI (0.169) < ektome (0.195) < ultra_heretic (0.300) < davidau (1.48) < OBLITERATUS (1.54)
davidau's 1.48 divergence comes from merging and fine-tuning across 850 tensors (GPQA +18.2pp, MMLU-Pro +7.4pp, IFEval -5.0pp, GSM8K -4.4pp), which makes it effectively a different model. For broader options, see Uncensored models: 10 options. trohrbaugh was the only build whose card claim matched the measurement (1.1x of measured KL), while coder3101, ultra_heretic and apostate understated divergence by 4.5x to 13.7x. Copyright walls held across all builds (1–39% compliance), and huihui-ai refused lyrics and passages entirely.
The table below summarizes the 13 arms evaluated by Abliterlitics:
| Model | Method / edit size | KL measured | Judge ASR | Harmful-only |
|---|---|---|---|---|
| orcarouter | single direction (Arditi 2024) / 129 tensors | 0.0676 | 82.2% | 96.7% |
| apostate (heterodoxin) | KCRN / 41 edits | 0.0439 | 78.7% | 95.0% |
| ektome | agentic search loop / 128 tensors | 0.1947 | 76.1% | 98.3% |
| huihui-ai | standard direction removal / 70 tensors | 0.0535 | 75.6% | 98.0% |
| apostate_diode | conditional / gated neuron (layers 14-48) | 0.0389 | 74.3% | 94.7% |
| davidau | merge + heretic / 850 tensors | 1.4798 | 73.2% | 92.7% |
| rvn | ARA 2 passes / 60 edits | 0.0837 | 71.3% | 92.0% |
| ultra_heretic | Heretic (MPOA) / 99 tensors | 0.2996 | 70.5% | 92.7% |
| coder3101 | Heretic / 88 tensors | 0.0842 | 70.0% | 91.7% |
| Blackfrost-AI | undisclosed / 124 tensors | 0.1694 | 68.5% | 91.0% |
| OBLITERATUS | heavy edit / 841 tensors (98.9%) | 1.5427 | 63.9% | 84.9% |
| trohrbaugh | ARA / 60 tensors | 0.0586 | 57.5% | 76.3% |
| Qwen3.8-27B (base) | unmodified | — | 4.5% | 6.0% |
All tests ran on an RTX 5090 32GB system using dynamic FP8, with glm-5.3-flash as the judge. For local GGUF builds, see GGUF quantization: how to choose Q4/Q8. Complete data and code are in the Abliterlitics report, the Hugging Face dataset, and the GitHub repository.
How do you check a build before running it?#
Before you run an uncensored build, check how it was made, whether anyone has audited it independently, and what its chat template contains. Then confirm the format fits your VRAM and try a few ordinary prompts, so you can spot thinking loops or truncated outputs early.
- Check that the creator discloses the method. The model card should name the ablation tool, the approach, and the edited layers; Blackfrost-AI, for one, does not disclose its method.
- Look for third-party audits. Rely on independent benchmarks instead of repository claims, since advertised KL figures often understate what the audit measured.
- Read the chat template. Look in
chat_template.jsonandtokenizer_config.jsonfor embedded system prompts or hidden jailbreak personas. - Check the format and dependencies. Before downloading, see whether the weights are stored in FP16, need a config overlay, or omit the vision tower and MTP head.
- Test ordinary reasoning first. Persistent thinking loops or early truncation suggest an over-edited build.
What is Deepent Research?#
Deepent Research is a browser-accessible LLM chat service built to refuse as little as possible. It keeps going with research that a standard AI would cut off mid-answer.
- It refuses nothing. We run uncensored and abliterated models with guardrails reduced as far as possible, so prompts a standard AI answers with "I can't help with that" still get a response (Qwen3.5 / Qwen3.8-27B-abliterated, depending on your plan).
- Your input is never used for training. What you look up is used only to provide the service, never to train AI or for any other purpose. Personal data is protected, and our privacy policy is public.
- Try it free. No GPU and no install, just open a browser. In the logged-out trial your conversation isn't saved, so you can start casually.
→ Try it free, no sign-up: https://deepentresearch.com
No question can stop research.
Frequently asked questions#
Is an uncensored Qwen3.8-27B build an official release from Alibaba?#
No. Alibaba released the official base model, Qwen3.8-27B, on August 14, 2026, and it declines nearly all sensitive requests. Every uncensored or abliterated derivative on Hugging Face is an independent community modification. The creators edit the weight tensors or runtime configuration to remove refusals, and Alibaba has no part in that work.
How much do uncensored Qwen3.8-27B builds differ from one another?#
They differ a lot in reasoning stability and in how many answers they finish. In the Abliterlitics audit, light edits like orcarouter and apostate finished over 70% of responses, while heavier ones like OBLITERATUS scored measurably lower on benchmarks. Others got stuck in thinking loops that used up the token limit before an answer appeared.
What hardware is required to run a Qwen3.8-27B build locally?#
Roughly 16GB to 24GB of VRAM is a common range for quantized 27B builds, while unquantized weights need far more. The audit itself served every build in dynamic FP8 on a single 32GB RTX 5090. Check the build's model card and your quantization format before you download, and expect long contexts and extended thinking to raise memory use.
Does an uncensored Qwen3.8-27B build guarantee accurate answers?#
No. Abliteration removes refusal behavior so the model attempts an answer, but it does not fix factual errors or add missing expertise. An uncensored model can state a hallucinated fact just as confidently as a correct one. Check the output against primary documentation before you use it.
Disclaimer#
This article was drafted with AI assistance and then reviewed, fact-checked, and edited by the Deepent Research team before publication.
It is provided for educational and research purposes and is not intended to encourage unlawful activity or crime.
Where figures are cited, they come from third-party public reports and vendor-published values and may vary with measurement conditions.
How this note was edited and verified
We cross-check primary sources such as official documentation and papers, and organize only what the facts support.
This note was drafted with AI, then fact-checked, expanded, and edited by the operator before publication.
Related notes
Abliterated Qwen3.8-27B: Compare 4 Editions and Choose
Abliterated Qwen3.8-27B differs by creator. Compare huihui-ai, orcarouter, Heretic and RVN editions by edit range, quantization and published refusal rates.
Uncensored LLMs: 10 Best Models by GPU Memory (2026)
In 2026, the best uncensored LLM for most people is Qwen3.8-27B abliterated. 10 top picks by GPU memory, plus how uncensored and abliterated models differ.
What Is Abliteration? How LLMs Lose Their Refusals
Abliteration is a weight-editing technique that removes an LLM's refusal habit while keeping its knowledge intact. Learn how it works, in plain English.
Try it yourself
Deepent Research is an LLM chat service that refuses almost nothing. Everything covered in this note can be tried without downloading anything.